History / From the journal001
Hiller and Isaacson's own chronology names a mixed student quartet, not the full Walden String Quartet, at the piece's first hearing.
Event: 9 August 1956
History / Systems note002
Mathews's own 1963 paper and a 2007 oral history document why Bell Labs' MUSIC programs made a computer a general synthesis instrument.
1957 event
History / Systems note003
web.archive.orgundated document
The Library of Congress and Bell Labs give different years and machines for the demonstration behind computer-synthesized singing.
1961 event
History / Systems note004
The Xenakis research centre's own history dates UPIC's first prototype to 1977 and traces four decades of institutional continuations.
1977 event
History / Systems note005
MIT Media Lab's own project page traces Hyperinstruments from 1986 virtuoso tools to systems for non-professional players after 1992.
1986 event
History / Systems note006
Lewis's own writing and interviews describe Voyager's player-and-listener design as an independent improvising partner, not an instrument.
1988 event
History / Systems note007
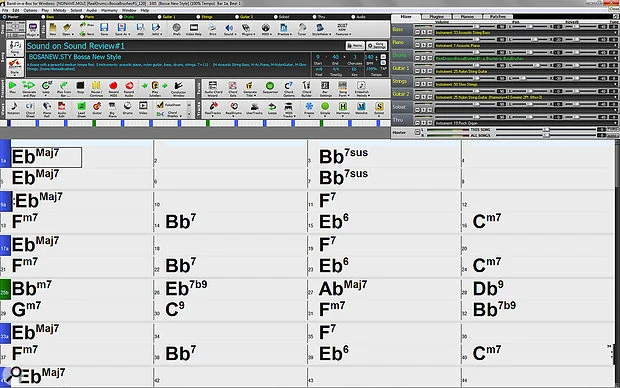
PG Music's own history and a 2017 review trace the product from 1990 MIDI-only output to recorded RealTracks added in 2006 and 2007.
1990 event
History / Systems note008
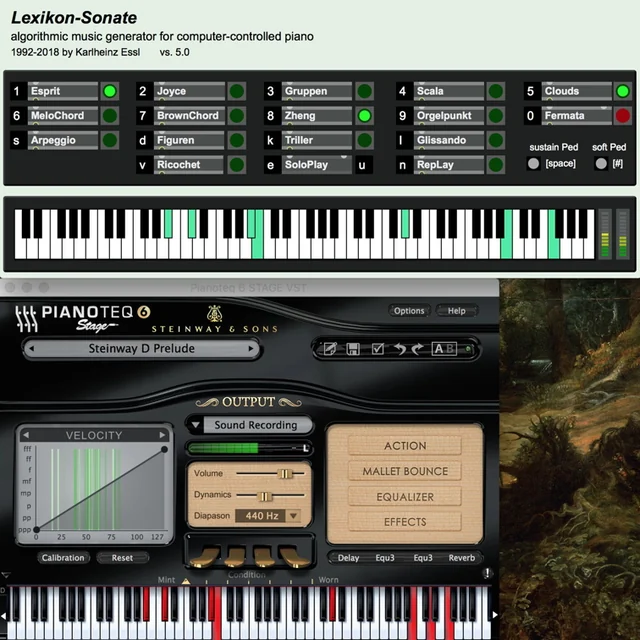
Essl's own site describes a 1992 generative piano system whose modular rules keep producing new, non-reproducible output decades later.
1992 event
History / Systems note009
web.archive.orgundated document
Cope's own account of his 1996 book names deconstruction, signature extraction and recombination as EMI's three-step method.
1996 event
History / Systems note010
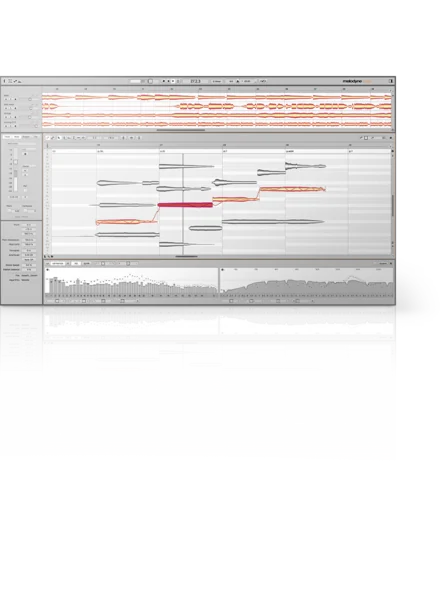
Celemony's own timeline and a November 2001 review confirm the original release edited only monophonic audio, years before Direct Note Access.
2001 event
History / Systems note011
Yamaha's own VOCALOID history and a 2007 engineering paper date the engine's 2003-2004 debut and name its synthesis method.
2004 event
History / From the journal012
Wolfram's own site and a 2011 blog post date WolframTones to September 2005 and describe cellular automata, not a trained model, as its method.
Event: 16 September 2005
History / Systems note013
Georgia Tech's own project and publication pages date Shimon to 2009 and trace its growth into composition and singing.
2009 event
History / From the journal014
find-and-update.company-information.service.gov.uk23 July 2019
Company records and a contemporaneous report date Jukedeck's 2012 founding and an unconfirmed 2019 move to ByteDance.
Event: 23 July 2019
History / From the journal015
web.archive.org11 November 2020
Shutterstock's 2020 release and Amper's own 2019 site describe a licensed sample library and an assets-only acquisition.
Event: 11 November 2020
History / From the journal016
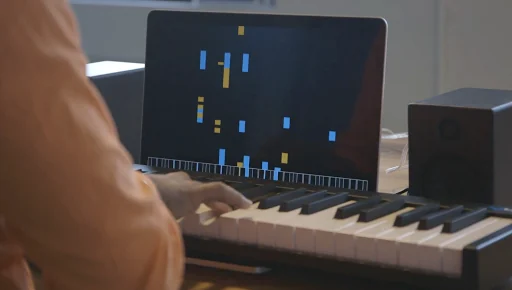
Google and Magenta's own posts date A.I. Duet's public release to February 2017, after a December 2016 conference demo.
Event: 16 February 2017
Model systems / From the journal017
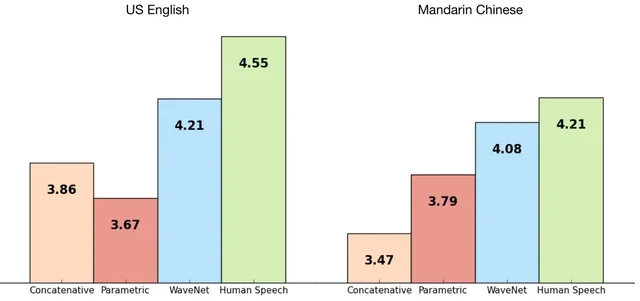
DeepMind's 2016 paper and blog report specific listening-test gains from raw-audio generation, not any later product's training data.
Event: 8 September 2016
Model systems / From the journal018
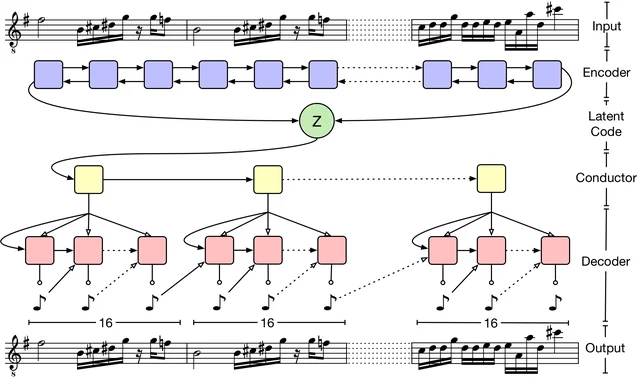
Magenta's 2018 paper and project page describe a hierarchical model for interpolating and sampling musical scores, not audio.
Event: 13 March 2018
Model systems / From the journal019
OpenAI's 2019 post names MuseNet's MIDI training sources and Sparse Transformer architecture, distinct from the later Jukebox system.
Event: 25 April 2019
Model systems / From the journal020
Harmonai's GitHub and Hugging Face pages document an MIT-licensed diffusion model with undisclosed training audio.
Event: 25 May 2022
Model systems / From the journal021
OpenAI's own paper and blog describe a crawled, unlicensed training corpus and hours-long render times.
Event: 30 April 2020
Model systems / From the journal022
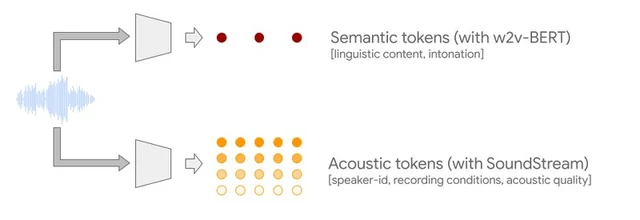
Google's paper pairs semantic and acoustic tokens and flags a detection safeguard only for its speech results.
Event: 7 September 2022
Model systems / From the journal023
arxiv.org26 January 2023
Google's paper discloses MusicCaps in full while leaving its 280,000-hour training corpus unattributed.
Event: 26 January 2023
Model systems / From the journal024
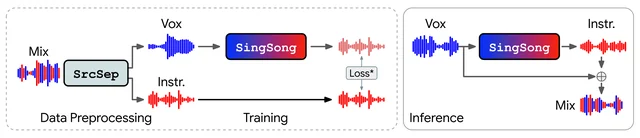
Google's paper documents a source-separation training method without naming the million-track corpus it drew on.
Event: 30 January 2023
Model systems / From the journal025
Meta's paper states a 20,000-hour licensed training pool by source, though the released weights stay non-commercial.
Event: 8 June 2023
Model systems / From the journal026
arxiv.org9 January 2024
Meta's masked-decoding paper cuts latency by up to tenfold while its own hours figure for licensed data drifts across documents.
Event: 9 January 2024
Model systems / From the journal027
Stability AI's paper lists exact Freesound and FMA recording counts, distinct from the commercial Stable Audio licence.
Event: 19 July 2024
Model systems / From the journal028
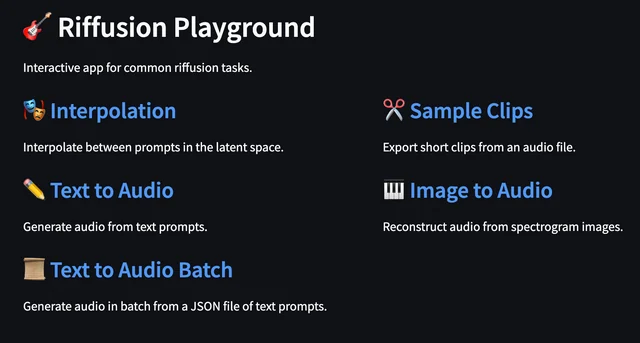
A Stable Diffusion fine-tune on spectrogram images, published under MIT licence, now survives only in its archive and repository.
Event: 1 December 2022
Model systems / From the journal029
Suno's own repository calls Bark a separate text-to-speech-plus system and discloses no training data for it.
Event: 20 April 2023
Model systems / From the journal030
The open YuE lineage adds an editable melody-and-chord plan, with its Suno comparison flagged as its own unproven benchmark.
Event: 26 January 2025
Model systems / From the journal031
DeepMind's 2023 announcement of Lyria and Dream Track named nine partner artists and a separate producer-tested toolkit, distinct from later model versions.
Event: 16 November 2023
Model systems / From the journal032
ElevenLabs' own launch post and docs describe Music v2's section-by-section composition and inpainting, apart from its commercial licence terms.
Event: 26 May 2026
Training data & rights / Systems note033
Magenta's MAESTRO dataset pairs about 200 hours of competition piano audio with millisecond-aligned MIDI under a non-commercial share-alike licence.
Entry note
Training data & rights / Systems note034
Colin Raffel's Lakh MIDI Dataset licenses his own compilation of 176,581 scraped files, not the copyright status of each transcription inside it.
Entry note
Training data & rights / From the journal035
arxiv.org6 December 2016
The 2016 FMA paper packaged over 100,000 Creative-Commons-tagged tracks from the Free Music Archive, though CC terms vary track by track.
Event: 6 December 2016
Training data & rights / Systems note036
Mozilla's Common Voice project crowdsources multilingual speech donations, validated by community vote and released under a CC0 public-domain licence.
Entry note
Training data & rights / Systems note037
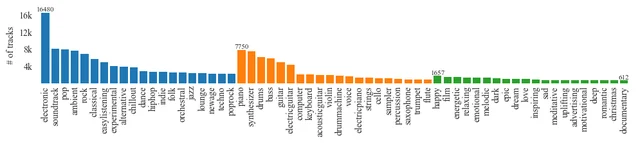
The MTG-Jamendo dataset's own GitHub documentation restricts its 55,000-plus Creative-Commons tracks to non-commercial research and academic use.
Entry note
Training data & rights / From the journal038
arxiv.org5 April 2017
Magenta's 2017 NSynth paper pairs a WaveNet-style autoencoder with a dataset of about 305,000 annotated single notes from sampled instruments.
Event: 5 April 2017
Training data & rights / From the journal039
Google's MusicLM paper describes MusicCaps as 5,521 AudioSet clips captioned by ten professional musicians for evaluation, not large-scale training.
Event: 26 January 2023
Training data & rights / From the journal040
research.google.com5 March 2017
Google's AudioSet documents 2 million labelled 10-second clips as YouTube references and precomputed features, not redistributed audio files.
Event: 5 March 2017
Training data & rights / From the journal041
copyright.gov31 July 2024
The Copyright Office's Part 1 report recommends a new federal right against unauthorized digital replicas but leaves existing law otherwise unchanged.
Event: 31 July 2024
Training data & rights / From the journal042
copyright.gov9 May 2025
The Copyright Office's Part 3 report rejects a blanket rule for AI training, weighing transformativeness against market harm case by case.
Event: 9 May 2025
Training data & rights / From the journal043
storage.courtlistener.com18 October 2023
Music publishers' 2023 copyright suit over Claude and song lyrics moved from Tennessee to California and remains active with no ruling on the merits.
Event: 18 October 2023
Training data & rights / From the journal044
The AI Office's mandatory template sets a common minimum for what general-purpose AI providers must disclose about training content.
Event: 24 July 2025
Training data & rights / From the journal045
gov.uk17 December 2024
A 2024 consultation's preferred opt-out exception for AI training was dropped in the government's 2026 report after rights holders objected.
Event: 17 December 2024
Training data & rights / From the journal046
SoundExchange's 2024 announcement of a voluntary AI training-consent registry set a Q1 2025 target its own materials have not since confirmed as met.
Event: 20 September 2024
Training data & rights / From the journal047
Universal Music Group's 2023 filing sets out two principles: only humans hold copyright, and AI training on copyrighted works requires a negotiated license.
Event: 30 October 2023
Training data & rights / From the journal048
Suno's CEO argued in a 2024 blog post that training on copyrighted music resembles a musician learning a genre, not the infringement labels allege.
Event: 1 August 2024
Economics & distribution / From the journal049
IFPI's Global Music Report 2026 attributes an eleventh straight year of growth to paid streaming while naming AI licensing and streaming fraud as watch items.
Event: 18 March 2026
Economics & distribution / From the journal050
Goldman Sachs Research's 2025 Music in the Air report forecasts revenue nearly doubling by 2035 and estimates AI music at 0.1% of the royalty pool.
Event: 28 August 2025
Economics & distribution / From the journal051
CISAC and PMP Strategy's 2024 study models a 2028 revenue-risk scenario, not an observed market outcome.
Event: 2 December 2024
Economics & distribution / From the journal052
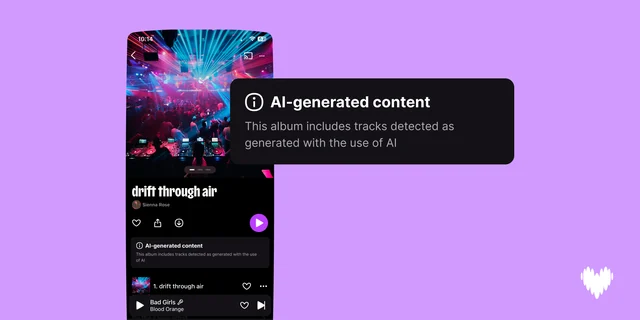
Deezer's newsroom states AI-generated uploads exceeded 50 percent of daily deliveries for the first time in June 2026.
Event: 1 June 2026
Economics & distribution / From the journal053
Spotify's newsroom states it removed over 75 million spammy tracks in twelve months, a self-reported figure, not an audit.
Event: 25 September 2025
Economics & distribution / Systems note054
DistroKid's help-centre article ties AI-track uploads to the same ownership and anti-impersonation rules as any release.
Entry note
Economics & distribution / Systems note055
CD Baby's parent publishes a content policy naming unlicensed AI training data and artist mimicry as specific prohibitions.
Entry note
Economics & distribution / Systems note056
Loudly's FAQ and licence agreement grant broad commercial use but forbid resale, sublicensing, and unauthorised film use.
Entry note
Economics & distribution / Systems note057
Mubert's own pricing FAQ and licence page tie monetisation to the Pro and Business tiers and bar redistribution on any tier.
Entry note
Economics & distribution / Systems note058
ElevenLabs' pricing and terms pages tie commercial rights to plan tier and reserve film, TV and radio for enterprise deals.
Entry note
Economics & distribution / Systems note059

Stability AI's licence page sets a one-million-dollar annual-revenue threshold separating free and enterprise use of Stable Audio.
Entry note
Economics & distribution / From the journal060
Suno's pricing page and September 2026 terms tie commercial exploitation to a per-tier monthly download allocation.
Event: 3 September 2026
Economics & distribution / From the journal061
Udio's own help centre confirms downloads were disabled during its licensed transition with Universal Music Group, before any replacement shipped.
Event: 17 February 2026
Economics & distribution / Systems note062
AIVA's own licence page ties copyright ownership, credit and monetisation rights to which subscription tier a composition was generated under.
Entry note
Creative choices / Systems note063
Spawning's own tooling and its 2022 launch reporting show what the artist-led opt-out project does, apart from Herndon's separate Holly+ instrument.
Entry note
Creative choices / Systems note064
Mycelia's own materials describe a prototype for embedding rights and payment data in music, years before AI made provenance urgent.
Entry note
Creative choices / From the journal065
Bloom's App Store listing and its creators' own site show a tap-driven generative system, distinct from the 1996 Generative Music 1 disc.
Event: 5 October 2008
Creative choices / From the journal066
Cave's own Red Hand Files letter states a ChatGPT song in his style is replication, not songwriting, and explains why in his own words.
Event: 1 January 2023
Creative choices / From the journal067
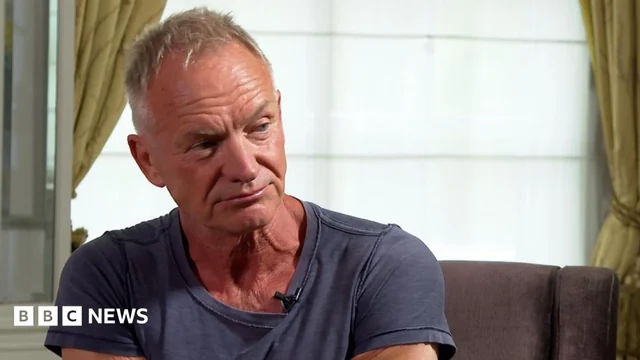
The BBC's own interview quotes Sting warning of a fight to defend human creative capital against AI, days before his Ivor Novello fellowship.
Event: 18 May 2023
Creative choices / From the journal068
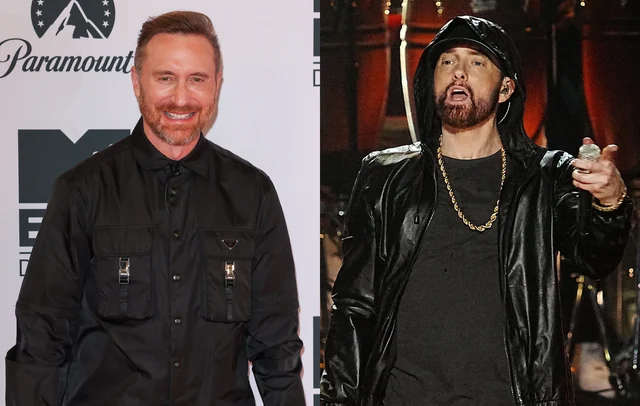
NME's contemporaneous reporting quotes Guetta describing how he built an unauthorised AI Eminem-style verse and why he will not release it.
Event: 1 February 2023
Creative choices / Systems note069
Kits AI's own ethics, earn and terms pages describe artist-submitted, revenue-sharing voice models rather than voices captured without consent.
Entry note
Creative choices / Systems note070
Voice-Swap's own pages show a credit-based personal tier alongside a contract-backed enterprise path for licensed voices.
Entry note
Creative choices / Systems note071
Moises' own help-centre articles state users keep output ownership while its generative models train on separately licensed data.
Entry note
Creative choices / From the journal072
Endel's own press release for its Grimes collaboration credits her original vocals and music as the seed material its engine adapts.
Event: 28 October 2020
Evaluation & evidence / Systems note073
ISMIR's own pages date its community to 2000, its incorporation to 2008, and list a downloadable paper archive for every year since.
Entry note
Evaluation & evidence / Systems note074
itu.intundated document
ITU-R BS.1534 defines the hidden reference and anchors that make a MUSHRA listening test a specific, checkable method, not a label.
Entry note
Evaluation & evidence / From the journal075
The original FAD paper defines a reference-free metric built for music enhancement, with a stated correlation to human perception.
Event: 20 December 2018
Evaluation & evidence / From the journal076
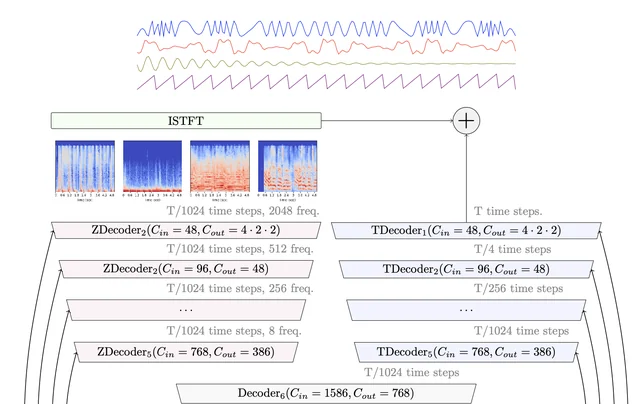
The Hybrid Transformer Demucs paper reports its 9.20 dB SDR score on MUSDB HQ, a figure from the authors' own evaluation, not a third party's.
Event: 15 November 2022
Evaluation & evidence / Systems note077
The mir_eval paper documents why inconsistent implementations of standard MIR metrics were confounding comparisons before the toolkit shipped.
2014 report
Evaluation & evidence / Systems note078
web.archive.orgundated document
Tzanetakis' own dataset page describes GTZAN's ad hoc origins, and a later peer-reviewed audit catalogued repetitions and mislabellings.
2002 report
Evaluation & evidence / From the journal079
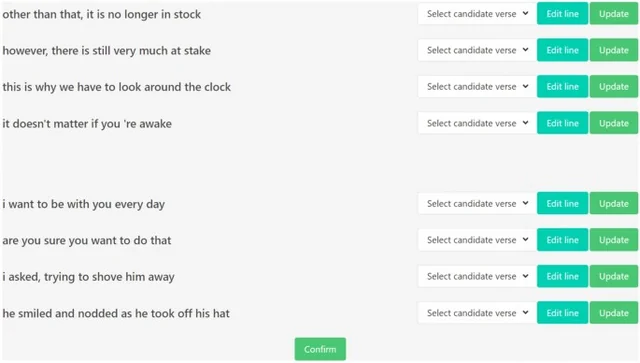
Two experiments found editing an AI poem lowered creativity, but co-creating with it restored creative self-efficacy.
Event: 9 August 2024
Evaluation & evidence / From the journal080
web.archive.org8 January 2025
An SSRN working paper found belief about a track's AI origin, not just its audio, changed how expressive listeners judged it.
Event: 8 January 2025
Evaluation & evidence / From the journal081
A 152-listener preprint found human-composed clips rated more effective at eliciting a target emotion than AI ones.
Event: 3 June 2025
Evaluation & evidence / From the journal082
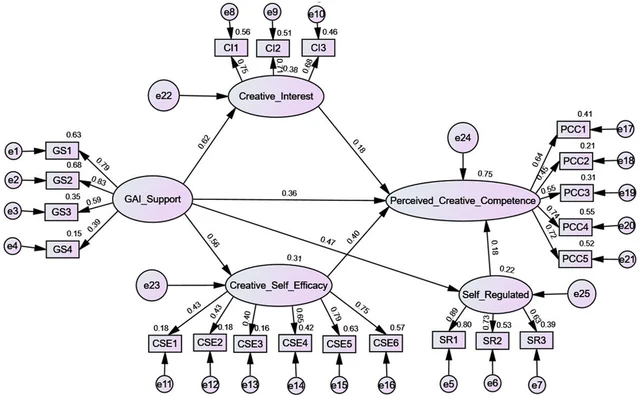
A Frontiers study of 405 Chinese music majors found GAI-supported collaboration raised several self-reported creativity measures.
Event: 9 December 2025
Evaluation & evidence / From the journal083
api.crossref.org8 April 2026
A 2026 paper reviews AI composition methods and proposes a new multi-level neural network framework, per its own abstract.
Event: 8 April 2026
Evaluation & evidence / From the journal084
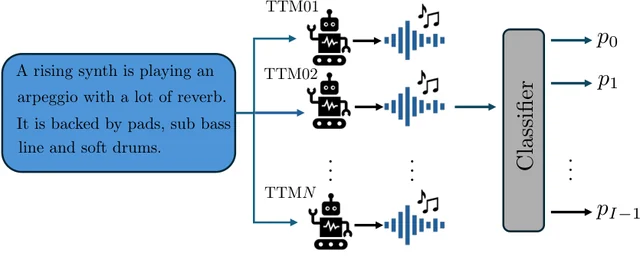
FakeMusicCaps pairs five text-to-music models' output with their MusicCaps prompts to benchmark detection classifiers.
Event: 16 September 2024
Standards & provenance / Systems note085
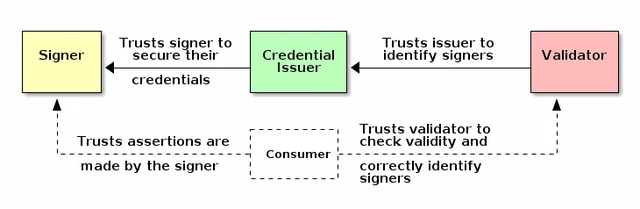
C2PA's version 2.3 specification sets out exactly how content credentials embed into MP3, FLAC and WAV files.
Entry note
Standards & provenance / Systems note086
ddex.netundated document
DDEX's Electronic Release Notification standard structures how labels send release metadata to streaming services.
Entry note
Standards & provenance / Systems note087
isrc.ifpi.orgundated document
The ISRC Handbook shows the code identifies a recording but explicitly does not establish copyright or authorship.
Entry note
Standards & provenance / Systems note088
iswc.orgundated document
ISWC registration requires uniquely identified creators and is explicitly unrelated to a work's copyright status.
Entry note
Standards & provenance / From the journal089
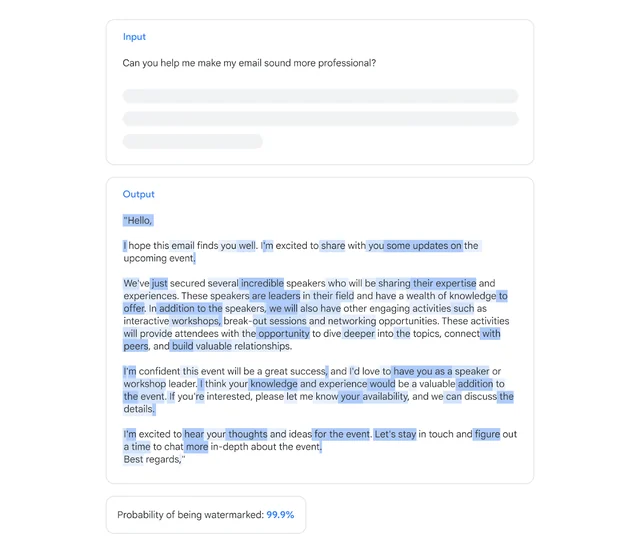
DeepMind's Nature paper and open-source release cover text watermarking, distinct from its separate audio watermark for Lyria and NotebookLM.
Event: 23 October 2024
Standards & provenance / Systems note090
acrcloud.comundated document
ACRCloud's own documentation describes a fingerprint-matching and AI-detection service that feeds rights decisions made by others.
Entry note
Standards & provenance / Systems note091
IRCAM's CUIDADO-era research supplied a descriptor taxonomy that MPEG-7 adopted, work that predates and underlies today's audio-recognition tools.
Entry note
Standards & provenance / Systems note092
itu.int1 November 2023
ITU-R BS.1770 defines the K-weighted loudness algorithm and LKFS unit that platforms build their own normalization targets on top of.
Entry note
Standards & provenance / Systems note093
acoustid.orgundated document
AcoustID's open Chromaprint algorithm and free lookup service identify already-known recordings by fingerprint, not by how audio was produced.
Entry note
Standards & provenance / From the journal094
midi.org1 January 1991
General MIDI standardized 128 instrument patches and drum mapping on top of the 1983 MIDI 1.0 protocol, unrelated to a file's authorship.
Event: 1 January 1991
Standards & provenance / Systems note095
web.archive.orgundated document
AES's own forensic-audio standards define authentication and evidence-handling methods for analog and digital recordings, not AI-detection.
Entry note
Standards & provenance / Systems note096
Spawning's own tooling shows a voluntary opt-out signal that a cooperating trainer's pipeline can check, with DeviantArt a documented adopter.
Entry note
Standards & provenance / Systems note097
Fairly Trained's published criteria define what licensed, public-domain or owned training data must look like to earn its certification mark.
Entry note
Standards & provenance / Systems note098
ISNI assigns persistent IDs to named creators and entities; any human-versus-AI flag would sit in a separate metadata field, not the ID itself.
Entry note
Economics & distribution / Systems note099
support.boomy.com9 April 2025
Boomy's own support articles say only Creator and Pro downloads carry full commercial rights, a policy that replaced exclusive distribution.
Entry note
Evaluation & evidence / From the journal100
The MERT paper pairs an acoustic and a musical teacher model to pretrain a music-understanding network across 14 benchmark tasks.
Event: 31 May 2023